2026-10-22
Written by Sofia Rodriguez
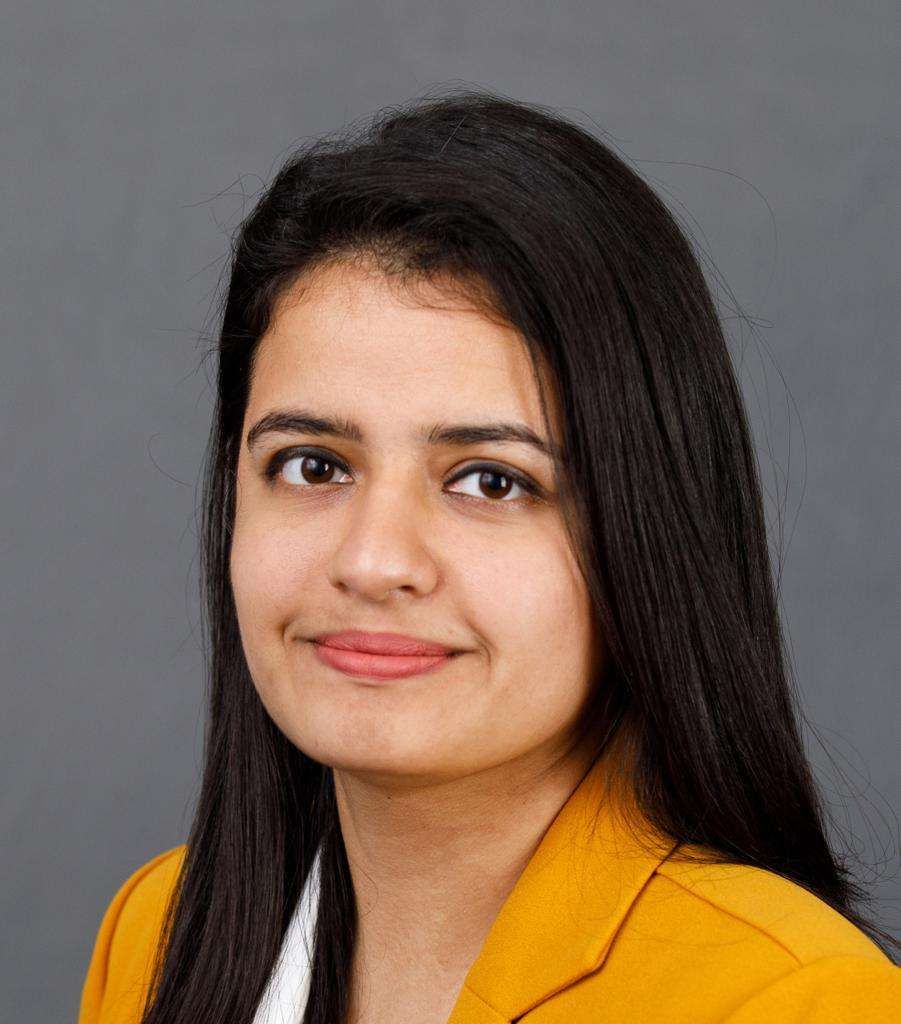
In government offices across India, meetings often move freely between Hindi and English, and someone spends an hour turning scattered notes into formal minutes. Vidisha Vijay, a senior data scientist who builds and evaluates AI systems, designed a bilingual assistant to shorten that hour and to work the way people actually speak.
Vijay’s assistant listens to meetings in Hindi, English, or mixed speech and converts the audio into structured minutes: a participant list, key discussion points, decisions, and an action item table that assigns owners and deadlines. A second mode accepts uploaded PDF or Word files and condenses them into short briefs that highlight figures and decisions. Officers can edit outputs before downloading, and unsaved work is preserved if the page is closed.
The tool has been adopted by officers in Central Goods and Services Tax offices in the Central Goods and Services Tax division in Mirzapur and the CGST audit commissionerate in Kanpur. Officers in Varanasi, Gorakhpur, and Aligarh have tested it and passed it to colleagues. Several users singled out the assistant’s Hindi transcription as accurate, and one superintendent said even staff not comfortable with technology could use it easily.
Anupam Kumar Tiwari, Assistant Commissioner of the CGST division in Mirzapur, said in a written statement that he had personally used the tools and found them efficient, reliable, and easy to use, praising the quality and precision of their output and how easily they fit into routine work.
Word of mouth helped spread the assistant, and that informal adoption became a source of concrete requests. Officers asked for Word document support and for downloaded files to be named based on their content rather than a generic label; both features were added. Other requests, such as removing repeated points so each item appears only once, are queued for future updates.
“Every piece of feedback was specific: this table is hard to read, this point repeats, I need Word files,” Vijay said. “That’s the best kind of feedback, because you can fix it the same week.”
Vijay’s research focuses on how AI models handle sensitive information. In a study presented with colleagues at the 2026 IEEE International Conference on AI and Data Analytics, she examined 2,800 tests across seven models from OpenAI and Google: GPT 3.5, GPT 4, GPT 4 Turbo, GPT 5.1, GPT 5.2, Gemini 2.5 Pro and Gemini 2.5 Flash. Each model received synthetic personal records, including job applications, and the research measured how much sensitive information the models repeated in their outputs.
The differences were stark. With no privacy instructions, Gemini 2.5 Pro repeated fewer than one in ten sensitive details in job applications, often redacting Social Security numbers unprompted. Gemini 2.5 Flash repeated every one. When asked to comply with US and European privacy rules, GPT 5.2 repeated none, while GPT 3.5 still exposed 30% even with the most detailed instructions.
Vague instructions produced other failures. Told only to anonymize hiring records, Gemini 2.5 Pro stripped out job roles it should have kept, retaining them in just 15.5% of outputs. Naming the exact fields to remove raised that to 76%. “My research showed the same model can behave completely differently depending on how you instruct it,” Vijay said. “You can’t trust an AI system you haven’t measured.”
The study is careful about its limits: the data was synthetic and tabular, deliberate extraction attacks were not tested, and model behavior can change with provider updates. It extends a 2023 paper that tested ChatGPT alone, and it sits alongside Vijay’s other work on evaluation and prompt design.
Making language models behave reliably has been a through line in Vijay’s work. In 2024 she examined whether prompt design could reduce bias in GPT outputs. In June 2026 she spoke to the ACM Richmond chapter on “Building Reliable Agents: Evaluation Frameworks for Multi-Step LLM Pipelines,” arguing that small errors early in a multi-step agent can quietly propagate through later outputs.
Alongside her independent research, Vijay leads the development of AI products at a major healthcare company. She trained as a chemical engineer at BITS Pilani and earned a master’s in business analytics from UC Davis. She serves as a peer reviewer for EMNLP 2026 and for Springer Nature’s Discover Computing journal.
For Vijay, development and evaluation are two sides of the same task. “Building the tool is the easy part,” she said. “Making sure it does what people think it does is the real work.”